Jekyll2026-08-31T18:43:19+00:00https://berislavbabic.com/feed.xmlberislavbabic.comMy ramblings about web development, ops, philosophy, business and whatever comes to mind.Berislav BabicWe need less screens and more paper2026-08-04T06:30:00+00:002026-08-04T06:30:00+00:00https://berislavbabic.com/we-need-less-screens-and-more-paperLast few years I’ve been consulting for a company whose main product is a workshop planning tool. Some time ago we were starting to discuss a mobile app for participants that will make them more immersed in the workshop. I understand we need to capture the attention of users, and get a foot in the door to potential customers as well. Yet, nowadays I have a completely opposing view of this. Silence and tuck away your phones so you can’t see them. Put it in a radio frequency blocking bag as well, so we can’t even get those pesky notifications while we are working.
Screens everywhere are designed to distract us from the things we actually want to do. I don’t think anyone wants to look at a small screen for their whole waking day. Yet the content on those screens is engineered in a way that we are hooked and need to put in a lot of effort to detach.
I’m gonna run a quick thought experiment on how we could achieve both. We want to give some workshop information/tooling to participants, but don’t want them to pull their phones out. Pulling the phone out will lead to seeing a notification, clicking on it, and then “checking email / the company group chat”. And then we have phased out doom-scrolling, ask me how I know. Recently I am trying to get better with pulling myself out of this doom-scrolling. And it is bad on many levels for me because it breaks my flow and I need a lot of time to get back into what I was doing. If I even manage to break out of doom-scrolling. Same goes for people you are trying to teach something.
The obvious screen replacement that pops up here is what screens replaced in the first place. And these are paper handouts. We want to be eco friendly in our approach and avoid killing more trees than necessary. But what if the trees already died and reincarnated into recycled paper? Since you can recycle paper again (5-7 times), if discarded in the correct waste basket, we are doing almost zero damage to the environment. You can use a paper cutter if you have super confidential info on the handouts. And there is something about writing down stuff on paper that makes you remember them better. Typing them on the computer also helps, but in my case, I get much better results when I use pen and paper instead of the keyboard.
The feeling of actual handwriting on actual paper is something surreal. I remember a period of not picking up an actual pen for years. I had to think real hard how to sign my name on some documents after those few years.
Countries that introduced tablets in schools are now banning their usage and going back to traditional ways of teaching. It took Finland 10 years to reverse course on that decision. I’m not saying that screens are bad. They at least weren’t as bad when I started, but there was much less to do back then, and you had to work hard to find information on the internet. Ads and banners existed, but the algorithms that would feed you useless junk to keep you engaged weren’t there yet, at least not in the amount we have today. Today we have to install tools and extensions to protect ourselves from all those intrusions. Ad-blockers, various browser plugins that make some apps less obtrusive and remove the “recommended for you” noise. These plugins don’t conform with the terms of service of a specific site. So when the specific site is also owned by the company creating the browser, they will do everything they can to block the plugin. Search for Youtube vs uBlockOrigin constant battle lead to browser manifest V3.
There is a benefit to having screens when trying to learn something new, but we should avoid pulling out our screen when we are amongst other people. This is gonna sound wild, but hide your phone like you hide your privates. If you pull out your phone in a group, you are making everyone uncomfortable and aware that you are not focused. I wouldn’t be writing this if I didn’t have the same problem. What helps is having a greyscale filter on the phone. Without colours, the screen can’t pull me in so hard, I don’t get as much dopamine from looking at it, and my brain doesn’t pull me towards picking it up. Takes a while to get used to, and I have a toggle that switches it back if I want to look at colourful photos. Otherwise it’s more or less grey for me.
If you want to read more articles like this, drop your name and email below, I promise I will never send you spam.
]]>Berislav BabicKeeping your email deliverability high by filtering invalid emails2026-07-30T07:00:00+00:002026-07-30T07:00:00+00:00https://berislavbabic.com/keeping-email-deliverability-high-by-filtering-invalid-emailsKeeping data consistent, compliant and true is pretty hard nowadays. We are aware of legacy code and tech debt problems, but rarely concern ourselves with data debt. This problem doesn’t show much if you have a 100% subscription business and you delete users whose subscriptions have expired . I know that some companies want to keep all the data forever, but this is both a huge privacy compliance hole, and can also be a performance hole. I’ll write about the performance problem deeper in another post.
For now, let’s talk about emails. Most web applications use a similar flow. When a user signs up to your application, they enter their email and continue with whatever authentication is popular at the moment. This might be entering the password, might be a one-time token sent to their email or creating a passkey. Now you have a user in your system, and if you allowed them to create an account using their email and password, you have to verify their email. A common way is not letting the user in unless they confirm their email. Yet there are still some big companies that don’t care about email confirmation upfront because they want to capture the users.
But what happens if you have a very old (more than a decade old) dataset on a freemium product with a lot of unverified emails? Well, then you have at least three possible problems:
Unverified but valid emails
Unverified but emails that were valid at signup (joe@company.com doesn’t work there anymore, their email was removed from the server)
Unverified and invalid emails (someone signed up using someone else’s email)
If you find yourself in this situation, don’t worry, we have many tricks up our sleeves to clean up the dataset and make sure it never gets too dirty.
First things first, if you don’t have email verification turned on (and re-verification on email change) make sure it’s enforced on all new accounts. You have to start capturing healthy data somehow. Then delete unverified email accounts after a short period (create a weekly task or something). And making sure that we don’t send anything except the verification one to that address.
Now for the legacy data cleanup. Something I love is getting an email that my account is being marked for deletion in X days. And this arrives from a company I signed up for a couple of years ago, to test their product. This might even make me log back in to see whether something changed, if I even remember what it was.
Let’s see how we can apply this process to our situation. First you create a new policy where you delete the user data after 12 months of inactivity. Nowadays it’s hard to even make the users use your application and pay for it, so you don’t want to force anyone to click or anything. But we can use this policy update email to filter out bounced/invalid emails . It will drop your email provider reputation for a short while. But since you are sending a valid email to all your users and it’s easier to dispute this than a spam email. After the email went out to all users, your email service provider now has invaluable data you can now use to your advantage. And this is the bounces/invalid emails lists in their system. Let’s say you have 2000 users, send them the policy update email, and you get 250 bounced and/or invalid emails. This would mean that your email delivery rate is 87,5% which isn’t that good, but it’s also not the end of the world. Let’s turn this into our favour, export those lists and mark the users as having invalid emails. Now if a user has been inactive for a long period of time (longer than your stated policy) and also has an invalid email, go ahead and delete them. And actually delete them, don’t update the email to @deleteduser.com. If a user is active, you have to somehow tell them that their email is invalid, and this is where you need to get creative. Pop-up message in your app that they need to verify/change their email is one way to go, with different levels of discomfort to the user (small popup, big popup, whole screen modal). You can embed a verification parameter into all the links sent to that email, and capture those clicks in your application. All these will add a bit of programming and server overhead, of course, but better to be safe than sorry.
And then you step into a final pitfall that I’m still uncertain about. When verifying the new email, do you verify the new email or the old one, do you send a message to the old one that the user changed their email? This is a problem for another day and another post. Let’s go back to our problem, you want to keep all the users you can (especially the ones paying you) and convert the trials to paid if possible. But you also want to keep your data clean and true.
And there is only one sane way out of this situation, and this means making sure all your users’ emails are valid. If they are not, and the users are active, make sure they verify their valid emails and change invalid ones. This makes both your database and your email provider happy. Your email sending reputation stays as high as possible with much less chance of ending up in spam.
]]>Berislav BabicRunning puppeteer on AWS Lambda to generate PDFs2025-08-15T16:00:00+00:002025-08-15T16:00:00+00:00https://berislavbabic.com/running-puppeteer-on-aws-lambdaI absolutely hate when someone starts prematurely extracting stuff into micro services. Long live the great monolith architecture and all that. But there comes a point where because of technology limitations, you have to think outside of the box. Well this is one of those times, although there was nothing inherently wrong with the approach we had, we hit various limitations on AWS (mostly disk throughput, but also the kerfuffle of calling JavaScript from Ruby to open Chrome and then hit a Ruby endpoint which runs JavaScript through a Ruby wrapper again). The crazy thing was that this worked, for quite a long time, until it didn’t. I’ll leave the debugging story for another day but this was the first thing that was deemed worthy of extracting into its separate “service”.
So how did I do it? It was really easy and straightforward to be honest. Packaging up some nodejs libraries, adding specific fonts we are using and pushing everything to aws using the aws cli on my computer. Because I want to keep things secure and don’t want to expose my endpoints to the internet, I’m calling the lambda through the AWS Ruby library and using an IAM server role to pass on the credentials. Again, another story of keeping your AWS closed down as much as possible and technically inaccessible to anyone but your app.
I’m using a stripped down chromium instance (there are some package size limitations on AWS Lambda which you can avoid using S3 as an intermediary, but it’s advisable to keep the layer size as small as possible).
Assuming you have your aws-cli set up and the credentials in place, let’s start building the lambda function.
Create the app folder (duh) cd projects && mkdir lambda-puppeteer && cd lambda-puppeteer
Run npm init and fill in all the project details. Enter index.mjs as the main option
Add and install the required packages: npm add @sparticuz/chromium puppeteer-core
Your package.json should look something like this now:
{"name":"lambda-puppeteer","version":"1.0.0","description":"AWS Lambda function to convert HTML to PDF using Puppeteer and Chromium","license":"MIT","author":“DonaldDuck”,"main":"index.mjs","scripts":{"test":"echo \"Error: no test specified\" && exit 1"},"dependencies":{"@sparticuz/chromium":"^138.0.1","puppeteer-core":"^24.12.1"}}
Okay, now that we have taken care of dependencies, let’s add the actual function code. Let’s say you want to send some already rendered html to the function and get a PDF out of it. The function can be modified to accept the URL and then do its best to output the URL to PDF. However this is something for another article (or just send me an email and I can help you set it up).
importchromiumfrom"@sparticuz/chromium";importpuppeteerfrom"puppeteer-core";importfsfrom"fs";exportconsthandler=async (event)=>{letresult=null;letbrowser=null;try{// Launch the browser with extra optionsbrowser=awaitpuppeteer.launch({args:[...chromium.args,"--disable-gpu","--font-render-hinting=none","--allow-file-access-from-files",],defaultViewport:chromium.defaultViewport,executablePath:awaitchromium.executablePath(),headless:true,ignoreHTTPSErrors:true,devtools:false,});constpage=awaitbrowser.newPage();awaitpage.setContent(event.html,{waitUntil:"networkidle0"});// Save the PDF to a temporary file (with additional options)constpdfPath="/tmp/output.pdf";letpdfOptions=event.options;pdfOptions.path=pdfPath;awaitpage.pdf(pdfOptions);// Read the PDF file as a bufferconstpdfBuffer=fs.readFileSync(pdfPath);console.log("PDF generated successfully:",pdfBuffer.slice(0,100));// Log the first 100 bytes for debuggingresult=pdfBuffer;// Return the raw PDF buffer}catch (error){console.error("Error generating PDF:",error);return{statusCode:500,body:error.toString()};}finally{// close the browser whatever the outcomeif (browser!==null){awaitbrowser.close();}}return{statusCode:200,headers:{"Content-Type":"application/pdf",},body:result.toString("base64"),// Return base64-encoded PDFisBase64Encoded:true,};};
Now that all code is in place, let’s deploy it and make sure we can call it from our application. First you have to understand how all this is structured. AWS Lambda has something that they call “layers” and you can have multiple layers attached to the same function. This way anything you need loaded in the /usr folder in your function can be there. Let’s say you need additional fonts to render the app, put them in a folder named fonts, zip it up and upload + attach as a new layer to the function that needs them. A note about fonts, aws lambda runner has the basic linux fonts installed but they won’t work for non-latin languages and emoji support is minimal. Check out the Noto font family on google and download the stuff you need.
But be careful since Lambda has a 250MB hard limit so all uncompressed layers plus the runner script can’t be more than 250MB combined. More on that topic in another post.
You can even have multiple node_modules layers running in the same function. Keeping it as simple as possible and avoiding version mismatches I opted to leverage S3 to go around the 50MB layer size limit. So first we are going to create the chrome + puppeteer layer.
Since I’m a big fan of automating all the grunt work using whatever is most convenient (and bash is pretty convenient on unix systems), I made a script to package everything up and deploy a new lambda “layer” to AWS Lambda.
# !/bin/bash# Installs npm dependencies from the package
npm install# Creates a nodejs directory, moves node_modules into itrm-rf nodejs &&mkdir-p nodejs &&mv node_modules nodejs/
# Zip the nodejs folder
zip -r puppeteer-chrome.zip nodejs
# Upload the zip file to S3 (temporary step because the image is too big for normal upload)
aws s3 cp puppeteer-chrome.zip s3://YOUR_S3_BUCKET_NAME/puppeteerLayers/puppeteer-chrome.zip
# fetch chromium and puppeteer versions for our descriptionchromium_version=$(jq '.dependencies."@sparticuz/chromium"' package.json)puppeteer_version=$(jq '.dependencies."puppeteer-core"' package.json)description="Puppeteer-core version: ${puppeteer_version}, Chromium version: ${chromium_version}"# publish lambda layer versionbucketName="YOUR_S3_BUCKET_NAME"&&
aws lambda publish-layer-version --layer-name puppeteer-chromium-layer --description"$description"--content"S3Bucket=${bucketName},S3Key=puppeteerLayers/puppeteer-chrome.zip"--compatible-runtimes nodejs24.x --compatible-architectures x86_64
Now that we have a puppeteer + chrome layer uploaded (hopefully you got a successful response), we can create our Lambda function using the index.mjs code like this (be sure to have a lambda execution role created in the AWS Console)
Now we only need to attach the correct layer (we are assuming there is only one puppeteer/chrome layer at this time) to the function.
aws lambda update-function-configuration --function-name lambda-puppeteer --layers arn:aws:lambda:AWS_REGION:AWS_ACCOUNT_ID:layer:puppeteer-chromium-layer:1
Our function is ready to run and you can test it from your application using the AWS SDK of your choice. Since I’m using Ruby on Rails, I’m gonna paste a quick example using the Ruby SDK.
classLambdaPdfattr_reader:html,:optionsdefinitialize(html,options={})@html=html@options=optionsenddefto_pdfresponse=lambda_client.invoke(function_name: 'lambda-puppeteer',invocation_type: 'RequestResponse',# Synchronous invocationlog_type: 'Tail',# optional: to include logs in the responsepayload: {html:,options: }.to_json)# Parse the responseresponse_payload=JSON.parse(response.payload.read)# Check if the response is base64 encodedifresponse_payload['isBase64Encoded']beginpdf_content=Base64.decode64(response_payload['body'])rescueArgumentError=>eraise'ERROR: Decoding base64 PDF content not successful:',e.messageendelseraise'ERROR: Response is not base64 encoded',e.messageendpdf_contentendprivatedeflambda_client@lambda_client||=Aws::Lambda::Client.newendend
]]>Berislav BabicMitigating infrastructure risk2024-06-08T06:00:00+00:002024-06-08T06:00:00+00:00https://berislavbabic.com/mitigating-infrastructure-riskWhen you are building a product on the internet, you should aim to get it out as soon as humanly possible. Things you don’t want to care that moment include the infrastructure you are running your app on. You want to get it out in front of people, hopefully with a payment form so they can pay for your product as soon as possible. I’m not talking about this situation here, you should start with something that gives you the most leverage and peace of mind while you are acquiring your valuable first customers. You definitely don’t want to fiddle with network policies and want an out of the box solution as much as possible. If you are capable of provisioning your own virtual instances, you could try out Kamal deployment which builds on top of the docker I’m gonna talk about later. Otherwise stick with some platform as a service solution like Heroku
Some of the things you have to think about upfront are basic security and backup policies, you don’t want to lose your customers’ data, or even worse, get it leaked somewhere. After your product is established, you might want to think about the chance that the service provider you are using is/can go out of business. This happens a lot with companies over time, and you can never expect a provider to continue working indefinitely.
Of course AWS or Google or Azure won’t go down tomorrow, but having a good and resilient infrastructure strategy is something that can help you in the future. Maybe your company ends up acquired by a bigger player and you have to migrate your infrastructure to another provider. Maybe you have to migrate outside of the cloud altogether. Maybe you do something controversial and end up de-platformed and have to figure out a way to get back online as soon as possible. Let’s discuss some of the options we have here.
First things first, make the application artefact as portable as possible. My advice here would be to stick with Docker, do whatever you can to mangle your code into a docker image and run it from there. This way you are forced to “control” the app using environment variables, and since you can run the same docker container with the same outcome on any machine imaginable, you will get the same outcome. Like Java’s promise of write once run everywhere, but this time you don’t have to debug it on every platform you are running your app on. Using docker will force you to make a stateless image, completely controllable by environment variables. This approach doesn’t cost you anything upfront, but can come in handy later if you have to rebrand, add different regions or even offer an enterprise self hosted option of your product.
Okay, since most applications won’t run without a database, you need to put a database engine somewhere as well. Sqlite has become a production ready database, but if you want scalability and more powerful features, you can stick to the tested relational database systems. MySQL and PostgreSQL are amazing choices. You can run them in a docker container or run them as a service on all cloud providers, and they are almost infinitely scalable, if you know how to set up replication and/or clusters. Choose whatever you like and know more, all this technology works pretty much the same. The above goes for other supporting services, you might be using redis or some other key/value database for caching, search or managing background jobs.
Back to our resilience strategy, what can we do to make sure we can keep the lights on if a cloud provider we are using goes down?
Off site database and file backups. Cloud file storage is really cheap nowadays, and there is no excuse not having the production database regularly synced to a backup location. Same goes for user uploaded files. This goes into the realm of Disaster Recovery, so be sure that your backups can be restored, unless you are using Super Simple Storage Service of course.
Have the ability to build the docker image on any computer with access to the internet. Ideally you’d have multiple engineers in your company that are able to run a script and build the image. In my opinion, the image for any git SHA must be able to run on any environment, see the 12 factor app. Funny enough, this is the situation we have when we start building a project, and then we lose this capability along the way, adding different production only dependencies. Using a single image approach and controlling it with environment variables only keeps us in check.
If you have both of those things sorted out, restoring from a catastrophic event could take a few hours tops. Not that much in the grand scheme of things. Remember I wrote about getting acquired and having to move to another cloud provider. This thing happened while I was working for intuo, now Unit4. We (mostly I) had to move the whole infrastructure from AWS to Azure. What saved my ass in the end was Docker (and Kubernetes) which I leveraged to have an infrastructure independent deployment. Yes there were intricacies where S3 was different from Azure Blob storage and the network management is different, but in the end it’s more or less the same thing whatever you are using.
Keep in mind that you are renting someone else’s computer in the “cloud” and running your stuff on it. If you are big enough, you could be wasting a lot of money using one provider instead of another. You could even move off the cloud and run your own servers if you find that more cost effective. Having the ability to do both whenever you want gives you both the leverage over the cloud provider (so you can get the best rates) and freedom of mind to not worry about someone hiking up the rates without a valid reason. Changing infrastructure is going to cost you, but the savings can be huge, and no one can replace the piece of mind you have when you know you can do it on a whim over a weekend if you really want to.
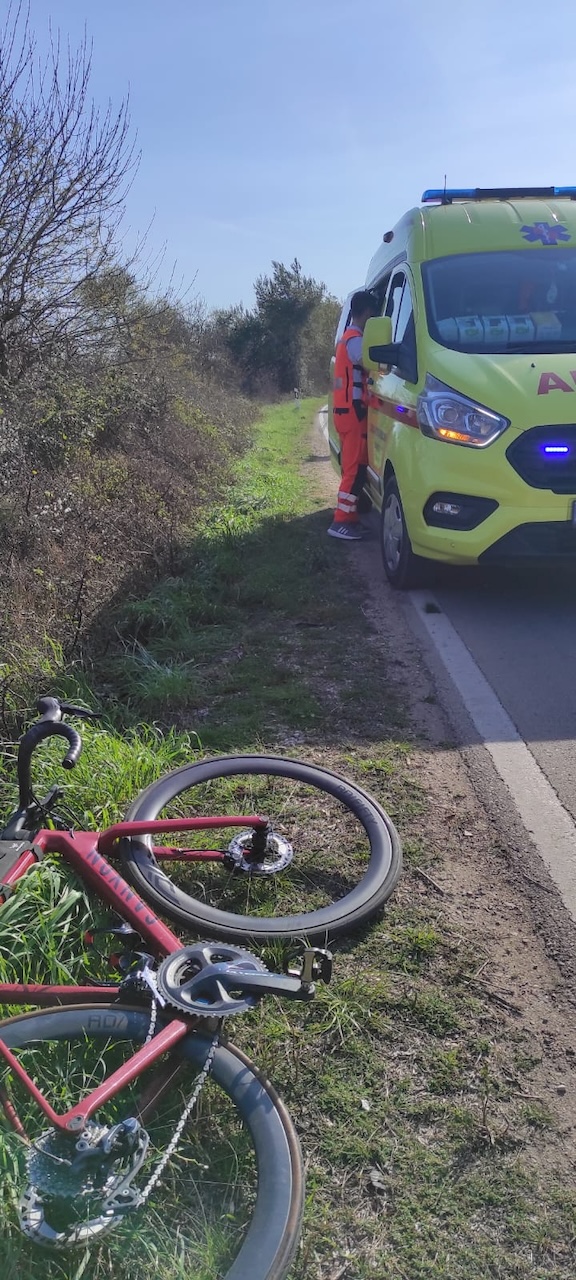
]]>Berislav BabicI got hit by a car2024-05-22T04:00:00+00:002024-05-22T04:00:00+00:00https://berislavbabic.com/i-got-hit-by-a-carExactly two months ago I was out on my very usual bike route and I heard the radar warning me that a car was behind me, then I heard the car braking hard and finally felt the car smashing into the bike, throwing the bike (and me) forward while it slid into a ditch by the road with its rear end. Next thing I know I’m on the ground and the car is revving hard, trying to get out of the ditch. After a few seconds the driver managed to get out of the ditch and drove away without even looking at me. Luckily I was composed enough to remember the car license plate and model (my dad was a car mechanic when I was a kid so I grew up around cars). So I did the usual, called emergency services which lead to spending hours in the ER to get checked and I found that I have an L1 vertebrae fracture. Waited 3 days for the neurosurgeon to come and tell me that I need to wear a brace and rest. Life lesson, don’t get into an accident in Croatia. Luckily the injury wasn’t something that would require surgery, just rest for 8-12 weeks and then back to (hopefully) normal life.
Since there isn’t anything I can do now to change the situation (I did my best to move as far right as possible, even going off the road onto gravel), I was thinking really hard on how I could have improved my chances of avoiding this situation. I already have a Garmin radar on the bike that warns me on traffic incoming from the rear. This device has saved my ass multiple times already, because especially on long rides, it’s easy to lose focus sometimes, and the audio signal brings the focus back immediately. I have multiple lights on the back regardless of time of day, and one on the front when it’s dark. And I make sure I’m as visible as possible. Doing all that, I still ended up on the ground, with a fractured spine and a destroyed bike. Weird situations happen all the time, a friend got knocked off his bike a couple of weeks before I had, the driver’s vision was obstructed by a sun glare and he couldn’t see the cyclist on the road so he “clipped” him with the side mirror. The difference between my friend’s case and mine is that the driver stopped immediately to check up on him and apologised. My driver on the other hand, is an asshole that fled the scene and denied the accident when caught by the police two days after. Okay, people panic, freak out and escape, but not having enough decency to accept your mistake and apologise later is not something to strive towards. I had the greatest luck that I wasn’t left bleeding unconscious on the side of the road, or dead on the spot. My family would never know what really happened.
Dark thoughts aside, accepting the current reality is what took me some time. Yeah I can be injured and need a few weeks to recover, but after a month it became really annoying. Talking to the second neurosurgeon (I wanted to have a second opinion regardless) helped me accept the current status and future options. There is a very high chance that I won’t have long lasting consequences. There is an absolute chance that I have to start training my core & support muscles if I want to heal this as soon as possible. I have to mostly rest (or do easy walks) for another month or so, and then we can reassess the situation. The new “normal” is somewhat boring, but I’m getting used to it, I’m just sad that I can’t help around the house as much as I did before.
The situation has given me time to ponder life and different options and I’m finally writing again. Not as much as I would like, of course. It takes a lot of time to get back into that habit. Taking it one day at a time though.
]]>Berislav BabicZero downtime redis migration (or upgrade)2024-01-27T06:06:00+00:002024-01-27T06:06:00+00:00https://berislavbabic.com/zero-downtime-redis-migrationI wrote about migrating the Redis database from AWS ElastiCache to another provider a few years ago . In my case it was Azure, but it doesn’t matter. I used a different, more hands-on approach there, since AWS limits config commands on their instances (to make it harder to move away I guess). I’m gonna show you another, faster way of migrating data from one Redis instance to another with near zero downtime.
Prerequisites
Let’s say you have 2 Redis instances set up, I’m gonna call them SOURCE and TARGET from now on. Those servers should be able to communicate with each other, at least on the 6379 (or whatever Redis port you are using).
Database replication
We are going to use redis-cli as our tool of choice here. Make sure the machine you are doing this from has access to both SOURCE and TARGET.
On the TARGET instance, we tell it to act as a replica of the SOURCE by running:
REPLICAOF SOURCE 6379
If you have password authentication set on the SOURCE, we need to provide the authentication option here as well
MASTERAUTH SOURCE_PASSWORD
Give it a minute or two and then you can run
INFO KEYSPACE
on both SOURCE and TARGET in parallel, to make sure the replication is running. Comparing the number of keys in each database is enough here. When you get the differences to be under 1% of the total keys, you can plan the next steps. The percentage depends on your application activity and how often it writes to Redis.
When you are certain the databases are in sync, we will turn of the read-only setting on the TARGET database. This isn’t recommended, but if you have a stable network connection between the databases, and are quick enough, nothing weird will happen. On the TARGET redis-cli we run
CONFIG SET REPLICA-READ-ONLY NO
This allows us to write data to the replica independent of the SOURCE which will keep writing the incoming data and syncing it over to TARGET.
Switch over to the new database
Next step is updating connection strings for your application. You replace the SOURCE with the TARGET (make sure you have updated authentication parameters so you can connect to the new db). If you can, run an isolated REPL instance to make sure your application can connect (this would be Rails console in my world).
After you are 100% your application can connect to the new Redis database, do a service restart or deploy to get the instance(s) running with the new connection string. The read-only setting that we turned off will allow old instances of the application to still write to the SOURCE and replicate the data to TARGET, and the new instances will write to TARGET so your migration is zero downtime (if your deploys are zero downtime, of course).
After the services have restarted, make sure the old processes have ended and nothing is connected to SOURCE anymore. Then you can run
REPLICAOF NO ONE
on the TARGET to promote it to master. You can clean up SOURCE after this step, but I would backup the database snapshot file, in case that you need to restore it later.
]]>Berislav BabicThe bus factor2024-01-20T17:26:00+00:002024-01-20T17:26:00+00:00https://berislavbabic.com/the-bus-factorWhen building any product or business, you want to make it as resilient as possible. You should do that from the very beginning, but sometimes this is hard, or we don’t have the time or resources to do it. As a result, we lock the key skills and competences within one person’s head. That person is most likely the founder or some key early employee, who took ownership of a specific area that no one else wants to touch with a 2-meter pole. In my case, it has always been infrastructure, or keeping the lights on. While this is a very interesting area for me to geek out on, it is boring or not as interesting for anyone else.
So, specific knowledge within the company resides inside one head. That’s a Bus factor of 1. In a nutshell, if that one person gets hit by a bus, your business takes a huge hit. People don’t have to die for this to happen, they could disappear from the project for whatever reason. Could find another job, or, well, get hit by a bus. In my experience, keeping this knowledge spread out is hard in small companies I usually work for. So the bus factor is almost always equal to 1 (sometimes 2 if there is a technical founder on board). What this means is that when one crucial person disappears from the project, you will lose years of knowledge, and intricacies of how the system is set up and how it actually works.
In small companies, everyone has a more or less dedicated role they do, but everyone is pretty aware of what is happening with other parts of the company. It’s easy to have an all hands call once per week or every other week with 10–20 people on the call. And teams are much smaller than that, so the daily check-ins serve to spread the knowledge of what the team is working on. Yet, as the company grows (and they usually do), the communication paths grow, teams multiply. Then you have 50% of the people unaware of even the existence of a complex system responsible for 30% of the revenue. They usually find out about that when someone decides to change something attached to it. According to Murphy’s Law, this happens when the complexity’s “owner” is on a 3-week vacation to a place with shady internet and 12 timezones away.
Mitigating the bus factor
There are a couple of ways to avoid the above situation. One is mandatory, and that one is test coverage and documentation. While you can skip documenting every thing under the sun and only document why and how you did the complex things in the app, you should never skip tests. I’m not preaching for full-blown TDD approach here, but having the “happy path” test coverage of a certain feature is mandatory in my book. It’s easier to write some things if you have tests upfront, sometimes it’s easier to write the tests after the fact. If you arrived this far, I guess you have enough of a brain to decide which approach to use. When documenting, also try to automate as many things as possible. A person running 7 different scripts to set up a testing/production environment can make 27 different mistakes running them. If you condense everything into one script, they won’t make the mistake (or not as many at least). Also, when you document something, you have a process. If you automate this processes, the people can use their brains for creative things and not to keep order of which script comes next.
The second thing is very smart to do, but hardly doable in small companies. Having many people covering the same responsibilities is great. But if you can’t achieve that because you lack people, then rotating people’s roles around the project would also work. Let’s say you have 3 engineers on the team, each specialized in their “favorite” job. DevOps, backend or frontend. Now all these 3 people can and will do all 3 roles if necessary, they like one of them more than the others. What if next time there is a “big” task in one of those, you pair two people with different preferences to do the task. Let the less experienced person “drive” and the more experienced one “navigate”. This way both of those people will grow by teaching or learning. The knowledge will get shared between the team, and you are increasing the bus factor to the number of employees within the company.
Whatever you decide to do, please don’t do nothing about this. It doesn’t matter whether you are a small company or a big enterprise, the bus factor is relevant in all cases. This is especially important for company owners. If you document all processes, and not rely on specific people to execute them, it will increase the company value. It will also make the company more stable and resilient.
]]>Berislav BabicHow to 10X your PR review quality2023-10-07T09:00:00+00:002023-10-07T09:00:00+00:00https://berislavbabic.com/how-to-10x-your-pr-review-qualityDuring my career in software development, proper communication (or lack of it) has been crucial in instigating some creative discussions and/or flame wars during reviews. Tensions were high sometimes, and egos were injured because of a person insisting on the single/double quotes or whatever they suggested/disagreed with.
Two hundred or even more comments later, nothing was accomplished except for some long lasting animosities between team members.
You can agree with me that we need a way to keep the code reviews from falling into the death spiral of constant change requests and toxicity. It wouldn’t hurt to make it clearer what the reviewers are actually saying to get their message across much easier, without any added noise.
Luckily I worked with a person that asked many (not so stupid) questions and insisted on having processes for everything and anything. Albeit that’s quite annoying upfront, having systems and processes allows you to automate and/or delegate them. It also gives you an operations manual of sorts. This article is based on one trick that I learned from him while I was at intuo.io and I’m trying to note it down now so it’s not lost.
To improve communication clarity, the engineering team agrees on a certain number of prefixes that we add when reviewing someone else’s code:
C:(change) - We absolutely have to change this, whatever this is. It’s related to something that breaks existing functionality, or could introduce bugs/performance issues in the future. So something that needs to be addressed before the PR is approved
Q:(question) - This is a general question to try to understand the issue at hand, no code changes are usually necessary for these types of comments
NTH:(nice to have) - I would like to have this implemented alongside the thing we are already implementing, this can be whatever you heart desires, but don’t expect it to be done, unless it actually adds to the quality of the feature
PP:(personal preference) - This comment is something akin to (I would personally implement this solution like this…, but your approach still works well). We can take this one as a teaching(learning?) experience where you might suggest a better (for you) solution for some problem
Thanks to Maarten Mortier for inspiring this approach and a lot of other procedures/systems I have built into the products I work on.
]]>Berislav BabicRescue exception in Ruby and continue2023-05-17T18:00:00+00:002023-05-17T18:00:00+00:00https://berislavbabic.com/rescue-exception-ruby-and-continueUsually when we run scheduled jobs we like to bunch a few things together for convenience. Let’s say that you have hourly, daily, weekly, monthly task list that needs to be executed. And that you use cron to execute those tasks. A good approach here would be to have those same cron tasks defined in crontab, one entry for each task. However we rarely do that because we have multiple tasks that can run together at the same time so we define a method that will run them one after another.
The thing we usually forget is that one of those methods, usually not the last one, will raise an exception and prevent the other methods from running. Something like:
Now imagine that the update_counters method fails and no emails get sent and the logs aren’t synced (whatever that means). We don’t want that situation to happen, but we also don’t want to blindly ignore exceptions doing something like this:
Of course we have linters and tools to warn us that this is bad practice, but we are trying to ship the product and it’s late Friday afternoon just before the big trip. A more sane solution would be to run those methods, catch any exceptions that occur and then continue.
You could define every method with a rescue clause:
If you encounter this problem in other places in the code, it’s always easy to extract it into a module and then include that module anywhere else in the code where you need the functionality.
]]>Berislav Babic5 things where Server Rendered apps beat SPA2022-10-12T14:00:00+00:002022-10-12T14:00:00+00:00https://berislavbabic.com/five-things-where-server-rendered-beats-spaI’m a huge proponent of server rendered apps. As someone that started with cluttered desktop apps close to two decades ago, and did his best to push as much of the processing to the database at that time, I know a thing or two about processing stuff on the client. Alongside the desktop stint (that took a better part of a decade), I was searching for (and finding) a better way of delivering apps to our customers. I didn’t have much say as a junior/mid person in that company at the time, but I fought my way into introducing something that in its core was a server rendered web application. This abomination was done in Oracle Apex, which was impossible to version, very hard to deploy to other databases, and induced full body headaches in every step of the process. But it was a start. After the Apex abomination, we played a little with .NET, and then I managed to sell Ruby on Rails to the management, which luckily stuck.
Now this isn’t gonna be a post about Ruby on Rails, or any technological choice in particular. You can probably render HTML from the server in any possible language you can imagine. There are frameworks in some, you have to raw dog it in others, but it can be done. There is a very well hidden secret that I’m gonna uncover now, you can even do server rendered HTML using JavaScript.
Let’s start with the list shall we?
You are using a single language/framework to render it
Now, I’m not saying you can’t do your frontend and backend code in JS if you wish to do so. But usually we choose a language for our backend, and JS for our frontend code. And it’s not only the language, it’s the whole framework on the backend and another whole framework on the frontend. I sincerely hope you are not doing your own bespoke SPA solution (and even more for the backend), because if you are, the technical debt you are adding increases exponentially with every line of code you write. If you are doing this, you are setting yourself for a nightmare scenario. More importantly, if you suffer from any success in the future, you will have to grow your engineering team. You surely don’t want to train people for 6 months before they are able to contribute to the project because that would be insane. You want them to hit the ground running and have their code in production in less than a week. The only way to accomplish this is by using well-established frameworks.
I said single for a reason. Although there are multiple people skilled in any framework you imagine, when it comes to a combination of them, it’s not that easy. Sometimes you’ll be able to find people quickly, most often you’ll have to train them in the skill they are lacking. I.e. if you are looking for a senior Laravel engineer, I believe you can find a 1000 of them available on the job market, but if you are looking for the same skill set, but both in Laravel and Vue.js, you’ll quickly realize that available people with those exact skill sets are in the single digits, and maybe don’t fit your budget.
It’s dead easy to deploy the app
Established backend frameworks already have the most common ways of deploying them (serving the production package to customers). There are platform as a service (PAAS) solutions for a lot of programming languages nowadays. Heroku supports 7 languages officially, but you can run multiple more using build-packs. You can always dockerize your app and serve it yourself from any of the multiple providers that offer containers as a service. Since you are rendering HTML from the server, you don’t have that much frontend code that you need to serve somewhere else, setting up a CDN to make it load super fast for users around the world. Now I’m not saying you won’t have to do this in the future if your app is successful, but it’s definitely not a thing you should think about from the start. You have to get your solution in front of users as fast as possible, so you can reduce their pains or save them money (or hopefully both).
Latency matters
Back in the day when I developed desktop apps, there was one thing that always caused a lot of issues. It was latency, combined with poorly written code of course. You can work a lot on the code quality, but there is nothing you can do to combat latency. Although desktop apps were more akin to web servers nowadays, since they connected to the database directly, there were a lot of places for improvement there. Later I learned that some of those issues were N+1 queries, but a lot of it was just hard processing that needed to fetch a lot of data from the server, crunch it, and then push it back to the database. In a “modern” web application, you will be fetching a lot of data you don’t need just to decide whether to render something on a page. This will make sense in the start, since you’ll have only a couple of pages consuming the same api endpoint, but soon you’ll find out that your assumptions about how customers will use the application (and how their data looks) are wrong in multiple dimensions. One way to combat latency issues in a SPA is side-loading in a JSON response. But before you know it, you’ll be side-loading data to render one specific page, then reuse the endpoint and crash the server trying to render a million records on another page. Of course you can go around this using parameterized serializers for different frontend page, which adds technical debt, slows down the development process and subsequently the application itself.
Doing things multiple times sucks
Imagine having to write every piece of logic twice. This is exactly what’s going to happen when you go the SPA path. You have to write validations in the frontend, so it works fast and doesn’t send faulty data to the API, but you also have to watch out for any malicious person and write the same (and sometimes additional) validation in backend code. If you were just using the backend framework to render HTML, you’d do the validation once and be done with it. Writing new features or perfecting old ones, making your customers happier and earning revenue. Validations are just one example, security is another. There are a lot of things you don’t have to think about when you are the one rendering the HTML and controlling what data ends up in the user’s browser. Authorisation is much easier to do as well, you can scope the permissions to the current page you are rendering in HTML, with API it’s less so. There are methods to secure the SPA in the same way you can secure SRE apps, but it’s hard and gruesome work, while with a SRE it takes a bit of common sense and that’s it.
Server rendered HTML is faster
Yes, yes, we all know how slick those transitions in dashboard apps look, and everyone wants shiny and new and fast. What if I told you that you can achieve the same slick transitions using some CSS magic, and sprinkle some vanilla JS here and there to achieve the same dynamic feel. If you are writing a business app, your main competitor is MS Excel. I’m not saying you should make your app obnoxious to look at, it’s just that it doesn’t have to have the same ‘feel’ that Instagram has. In my previous job we used to stress a lot if the whole html page wasn’t rendered under 100 ms, and 50 ms was the norm for us. Nowadays if the API server returns its load under a second, it’s considered good enough. Now imagine a customer is opening your app for the first time (which will be after every deployment since they need to reload the code that changed). They have to download a couple of MB of your app’s JS code, then the same amount if not more of the JS dependencies, and then the data itself from the server. This can take a lot of time to do on a slow connection. If it takes too long, they will give up and find something that will solve their problem faster. Clicking on a link and having the page render in the blink of an eye saves your customers’ time and money, letting them get in, do what they want and get out as soon as possible. No one likes using your app, it’s a tool that helps them achieve a goal, fix some pain they are having or save them money.
While we are on the speed topic, you can very easily cache HTML fragments. There are frameworks that allow you to cache nested fragments, with a very simple cache invalidation strategy that bubbles up. This way you will make less trips to the database, and use less processing/rendering power on the server, just reading the fragment from your lightning-fast cache store.